Knowing how to make JavaScript SEO friendly starts with a simple question: can crawlers access the content you want to rank? You can invest in detailed product pages and useful resources, but if their content depends on JavaScript that a crawler can’t execute, that work may never reach your audience.
Fixing this means pinpointing where access breaks down. Some sites need changes to internal links, metadata, or resource loading. Others need a different way to deliver rendered content, and a large, frequently updated enterprise site may need both.
At Prerender.io, we recommend starting with your most valuable pages: check what crawlers receive, identify what’s missing, and choose a solution that your team can maintain. Your framework, content update frequency, and engineering capacity should shape that decision.
This guide walks through seven practical JavaScript SEO fixes, explains when to reconsider your rendering approach, and shows you how to check that your changes work.
What is JavaScript SEO?
JavaScript SEO is the work of making JavaScript-generated content discoverable, renderable, and indexable by search engines. It covers how pages deliver their content, expose links, and communicate page-level information.
Google processes pages through crawling, rendering, and indexing. It can execute JavaScript, but content that depends on that execution requires additional processing before Google can assess it. Other crawlers may lack that capability.
Our team at Prerender.io knows that critical content deserves the fewest possible dependencies between a crawler requesting a page and receiving something useful.
Why JavaScript Content Can Be Invisible to AI Crawlers
Google may be able to render your product pages even when an AI crawler can’t read their descriptions or prices.
In a recent study, Vercel and MERJ found that GPTBot, ClaudeBot, and PerplexityBot did not execute JavaScript. Google’s infrastructure and Applebot could, so the findings don’t apply to every crawler.
Here’s what that means for your website. A shopper opens a product page, and JavaScript loads its description, specifications, price, and availability. The shopper sees a complete page. But if the HTML initially sent by your server contains only navigation and a “Loading…” message, a crawler that doesn’t run JavaScript misses those product details.
We recommend checking whether the HTML sent to crawlers contains the information a customer needs to understand your offering. For a product page, look for the product name, description, specifications, price, availability, and related-product links. For a job listing, check the role, employer, location, and application details.
Ask your developer to inspect that HTML response and search for specific details, such as a sentence from the product description or its current price. If they appear only after JavaScript runs, you’ve identified content that needs to be included in the HTML served to those crawlers.
Our guide to optimizing your website for AI crawlers covers additional access checks. Below, we’ll explain the JavaScript SEO fixes that help make your content discoverable and readable.
How to Fix Seven Common JavaScript SEO Problems
Start with representative URLs from your most valuable templates: a category, a product or listing, an article, and a recently updated page. Fixing a shared template can resolve the same issue across many URLs.
1. Allow Crawlers to Access Essential JavaScript and CSS
When investigating missing content, check whether the resources needed to produce it are accessible. Google won’t render blocked JavaScript files.
Review the relevant rules in robots.txt against the actual paths your application uses. A broad restriction on an assets directory deserves particular attention if that directory contains rendering dependencies.
Don’t paste a generic “allow JavaScript” snippet into production and assume the problem is solved. Ask your developer to identify the specific blocked resource, determine why the restriction exists, and make the narrowest appropriate change.
Retest the affected page afterward. Your acceptance criterion should be that the missing content now appears, not simply that the robots.txt file looks different. For examples and configuration guidance, see our robots.txt guide.
2. Make Internal Links Crawlable
A clickable element isn’t necessarily a crawlable link. For example, these patterns depend on JavaScript navigation:
<a onclick=”goTo(‘/products/running-shoes’)”>Running shoes</a>
<span onclick=”goTo(‘/products/running-shoes’)”>Running shoes</span>
Use an anchor with a real destination:
<a href=”/products/running-shoes”>Running shoes</a>
Google recommends <a> elements with an href attribute that resolves to a usable URL. JavaScript-generated links can still be crawlable when they follow that pattern. Your application can retain client-side navigation; the underlying markup should still communicate where the link goes.
Prioritize category navigation, breadcrumbs, related-item links, and pagination. These are the connections through which a crawler can discover the rest of your catalog.
Also, test the destination directly in a fresh browser session. A product URL should work when opened independently, without requiring someone to visit its category first.
3. Keep XML Sitemaps Aligned With Your Live URLs
Your sitemap should reflect the pages you currently want search engines to discover. Google recommends listing preferred canonical URLs and using accurate modification dates when you include lastmod.
For frequently changing sites, we recommend generating sitemap updates from the same publishing workflow that creates, updates, or removes pages.
Build the review around actual events:
- Does publishing a new listing add its preferred URL?
- Does removing a page remove an obsolete sitemap entry?
- Do meaningful content changes update lastmod accurately?
- Do sitemap URLs agree with the destinations used in internal links?
A route existing in your application doesn’t automatically mean it belongs in the sitemap. Filter combinations, internal search results, and duplicate URL variations need deliberate treatment. Think of the sitemap as a discovery aid: it cannot compensate for a destination that serves incomplete content or conflicting indexing instructions.
4. Give Infinite-Scroll Content Crawlable Pagination
Infinite scrolling can make browsing convenient, but discovery shouldn’t depend on a crawler scrolling or pressing “Load more.”
Google’s guidance is to give chunks of content persistent URLs and connect them through crawlable links.
For example, a shoe category might expose:
/shoes?page=1
/shoes?page=2
/shoes?page=3
Each URL should load its corresponding products directly. Users can still enjoy continuous scrolling while the underlying pagination provides another way to reach those items.
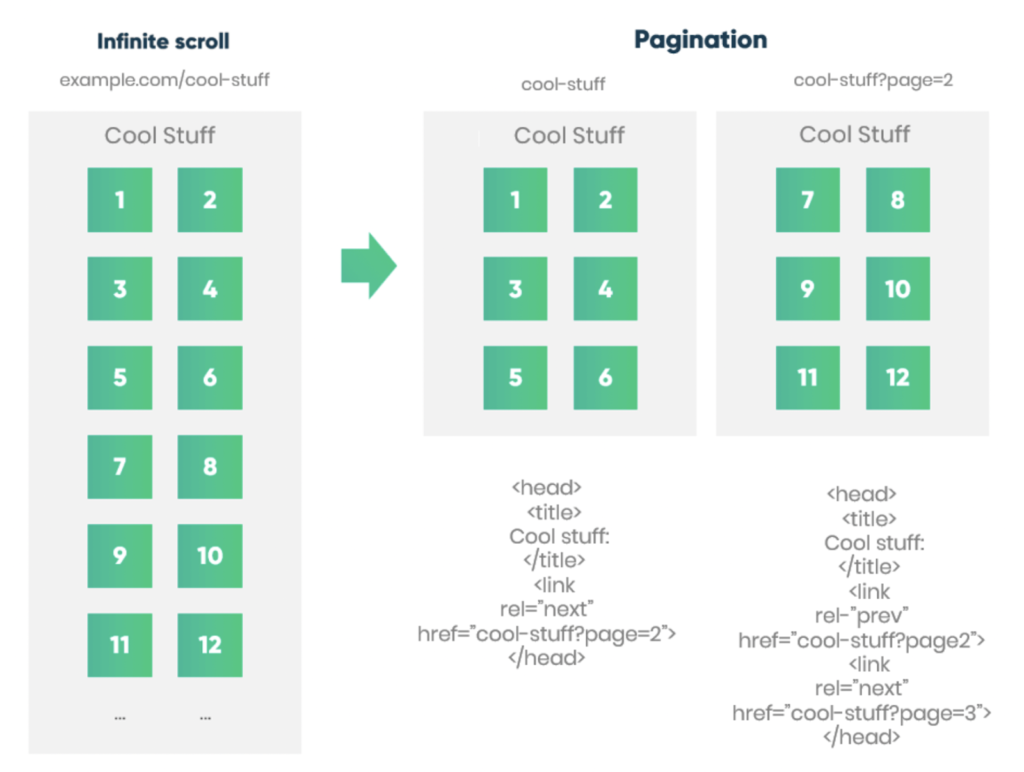
Test a product several batches into the list. Can you access its listing via the linked URLs without interacting with the infinite-scroll interface? That is more useful than confirming that the first screen renders correctly.
5. Reduce Unnecessary JavaScript and Rendering Work
We recommend asking a practical question about every dependency: does this need to run before the page can communicate its main purpose?
A product description shouldn’t have to wait for a recommendation carousel, review widget, and promotional overlay to initialize.
Start your investigation with the code and requests on that critical path. Ask your engineering team to assess opportunities to remove unused code, split functionality by route, and defer features that aren’t needed for the initial experience. Measure the result instead of assuming that a smaller file automatically resolves the problem.
Priority order should be:
- Make the main content reliably available.
- Remove unnecessary work required to display it.
- Improve the remaining interactive experience.
This also keeps performance work focused. Spending a sprint optimizing a secondary widget has limited value if the product data still arrives too late or fails entirely.
For related asset work, see our guide to optimizing media for JavaScript SEO and SPAs.
6. Provide Accurate Metadata for Every URL
Treat metadata as part of each page template’s acceptance criteria. For every important URL, we’d check the title, description, canonical URL, and indexing directives against the page’s intended purpose. Test both a direct visit and navigation from another page; this helps catch metadata that carries over between routes.
For example, moving from a category to a product should not leave the category’s title attached to the product.
Google supports JavaScript updates to some metadata, but warns against conflicting canonicals and relying on JavaScript to remove an initial noindex directive.
Our preference is to provide correct page-level information in the initial HTML wherever possible. It makes the implementation easier to inspect and reduces dependence on a later update.
Include metadata checks in template releases, especially when changing routing or shared layout components.
7. Version Updated Resources to Prevent Stale Rendering
A deployment can introduce new page logic while a crawler still uses an older cached resource. Google recommends content fingerprinting: changing the resource filename when its contents change.
For example:
catalog.8c41e2.js
catalog.b739ad.js
We’d make resource versioning part of the build process, then test a recently changed page after deployment. Also, distinguish between an outdated script and an outdated rendered page. They require different checks.
If you use Prerender.io, your cached HTML needs a refresh policy that reflects how the underlying content changes. Recaching updates that stored snapshot; it is separate from versioning your application’s JavaScript files.
Our guide to caching and prerendering explains the relationship. We recommend documenting both processes so the team knows which cache to investigate when information becomes stale.
How to Choose the Right Rendering Approach for Your Site
The seven fixes address individual failure points. Your rendering approach determines how much work is required to deliver the page in the first place. We recommend making that decision based on four factors: content freshness, catalog size, existing framework capabilities, and ongoing engineering ownership.
Start With How Fresh Each Page Needs to Be
“Frequently updated” is too vague to guide an implementation. An article corrected monthly and a product whose availability changes throughout the day have different requirements. Identify which fields change, what triggers those changes, and how much delay is acceptable before crawlers receive the updated version.
Static site generation can suit content that remains stable between builds. Where supported, incremental static regeneration allows static pages to update without rebuilding the whole site. Next.js documents both time-based and on-demand revalidation approaches.
For your decision, the relevant question is whether the chosen approach can consistently meet the freshness requirement.
Evaluate In-House SSR Against Your Existing Architecture
Server-side rendering produces page HTML on the server. Frameworks such as Next.js support combinations of server rendering, static generation, and client-side rendering, so the decision can vary by page.
If your application already has a suitable server-rendering setup, extending it may be sensible. We wouldn’t recommend changing architecture solely because a checklist says every JavaScript site needs a new rendering solution.
Ask your developers to demonstrate the response for representative URLs. The framework name alone doesn’t prove that product details, metadata, or navigation arrive complete.
Then establish who owns failures, cache refreshes, and regression testing. For a large catalog, the ongoing operating model matters as much as the initial implementation. Our enterprise SSR guide covers the deeper considerations.
Consider Prerender.io When Crawler Access Needs a Faster Path to Production
For an established React, Angular, or Vue application, an in-house rendering project may compete with substantial product work. Prerender.io renders JavaScript pages and serves rendered HTML to supported crawlers, allowing teams to address crawler access without rebuilding the application around SSR.
We recommend considering this approach when important public content depends on client-side rendering, the catalog is large or changes often, and your team has limited capacity for an architectural project.
The evaluation should still be specific:
- Which URLs need rendering?
- Which fields must appear in the snapshot?
- How will important updates trigger refreshes?
- Who will review failed or incomplete renders?
For us, those questions are central to a useful implementation. A rendered page must be complete enough and current enough to serve its purpose.
Our in-house SSR versus Prerender comparison explores the operational trade-offs. For a large or complex catalog, our enterprise team can help assess the requirements.
How to Check Whether Your JavaScript SEO Fixes Work
We recommend keeping a small set of test URLs and repeating these checks after changes to routing, templates, rendering, or caching. Include at least one recently published page and one recently updated page. Older URLs alone won’t tell you whether discovery and freshness are working.
Compare the Initial Response With the Rendered DOM
Open the page source and search for a distinctive sentence from the main content. Then inspect the same text in Chrome DevTools’ Elements panel.
This comparison helps establish whether the text arrived in the document or appeared after JavaScript ran. Where your infrastructure serves different responses to crawlers, inspect the crawler response as well. A normal browser request doesn’t verify that delivery path. Record the result for each required field: present, missing, incorrect, or stale.
Use URL Inspection to Check Google’s View
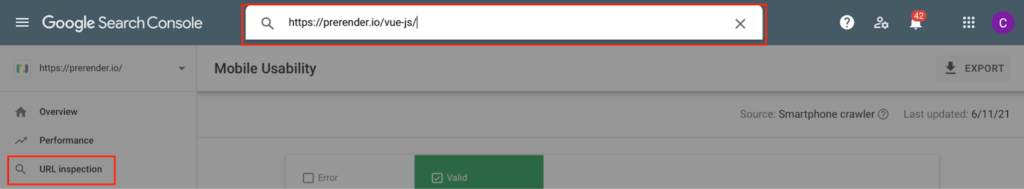
In Search Console, inspect the URL and review its indexing information. Then run a live test to assess the current page.
Open the tested page details and inspect the HTML, screenshot, and resource information. Search for the main content and check whether essential requests failed. The live test evaluates the current version; the indexed report reflects Google’s stored information. A successful live test does not guarantee indexing.
Let’s explore how to use them on your site. First, go to your Google Search Console and type the URL you want to check into the Inspector tool.
Then click on the TEST LIVE URL button.
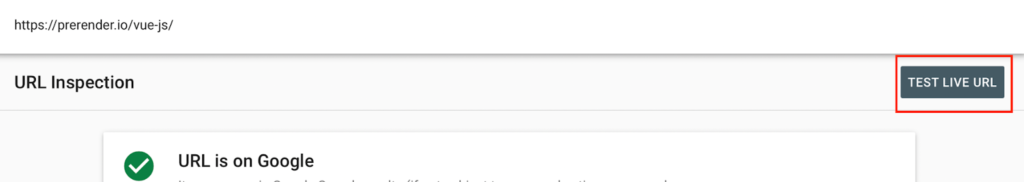
The tool will report on a few issues right away. For example, our target page has some mobile issues according to the tool.
What we’re going to do now is click on the VIEW TESTED PAGE button and then go to SCREENSHOT.
There we’ll be able to see whether or not Google can access our main content, the differences between your browser and the screenshot, and more.
Just next to this tab, there’s the HTML tab. This is a great place for you to find out what’s DOM-loaded by default.
Go there and try to find a snippet of content. If it appears, Google definitely has access to your site’s resources. If it doesn’t appear, then you have work to do.
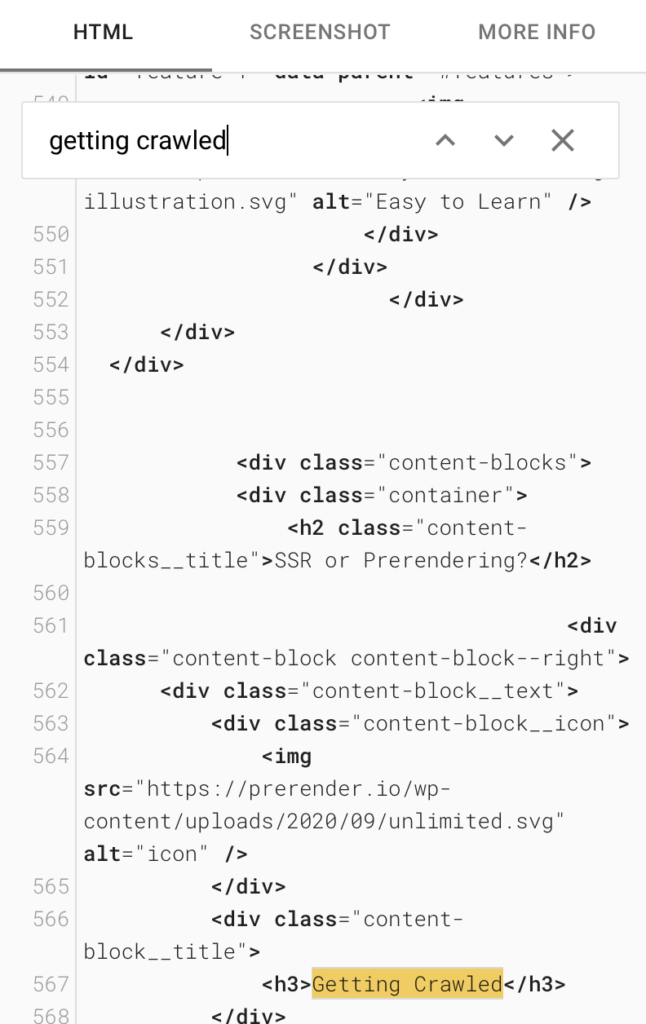
The tool will also report if there are any blocked resources. That will become handy when debugging your page.
Use the Rich Results Test when checking supported structured data, alongside inspection of its rendered output. Google also recommends its testing tools when diagnosing JavaScript rendering problems.
Use DevTools to Investigate Missing Resources
In Chrome DevTools, open the Network panel and reload the page. Identify the requests responsible for the missing content and investigate failures with your developer.
To test resources, in Google Chrome, go to the page you want to audit, right-click, and inspect the page.
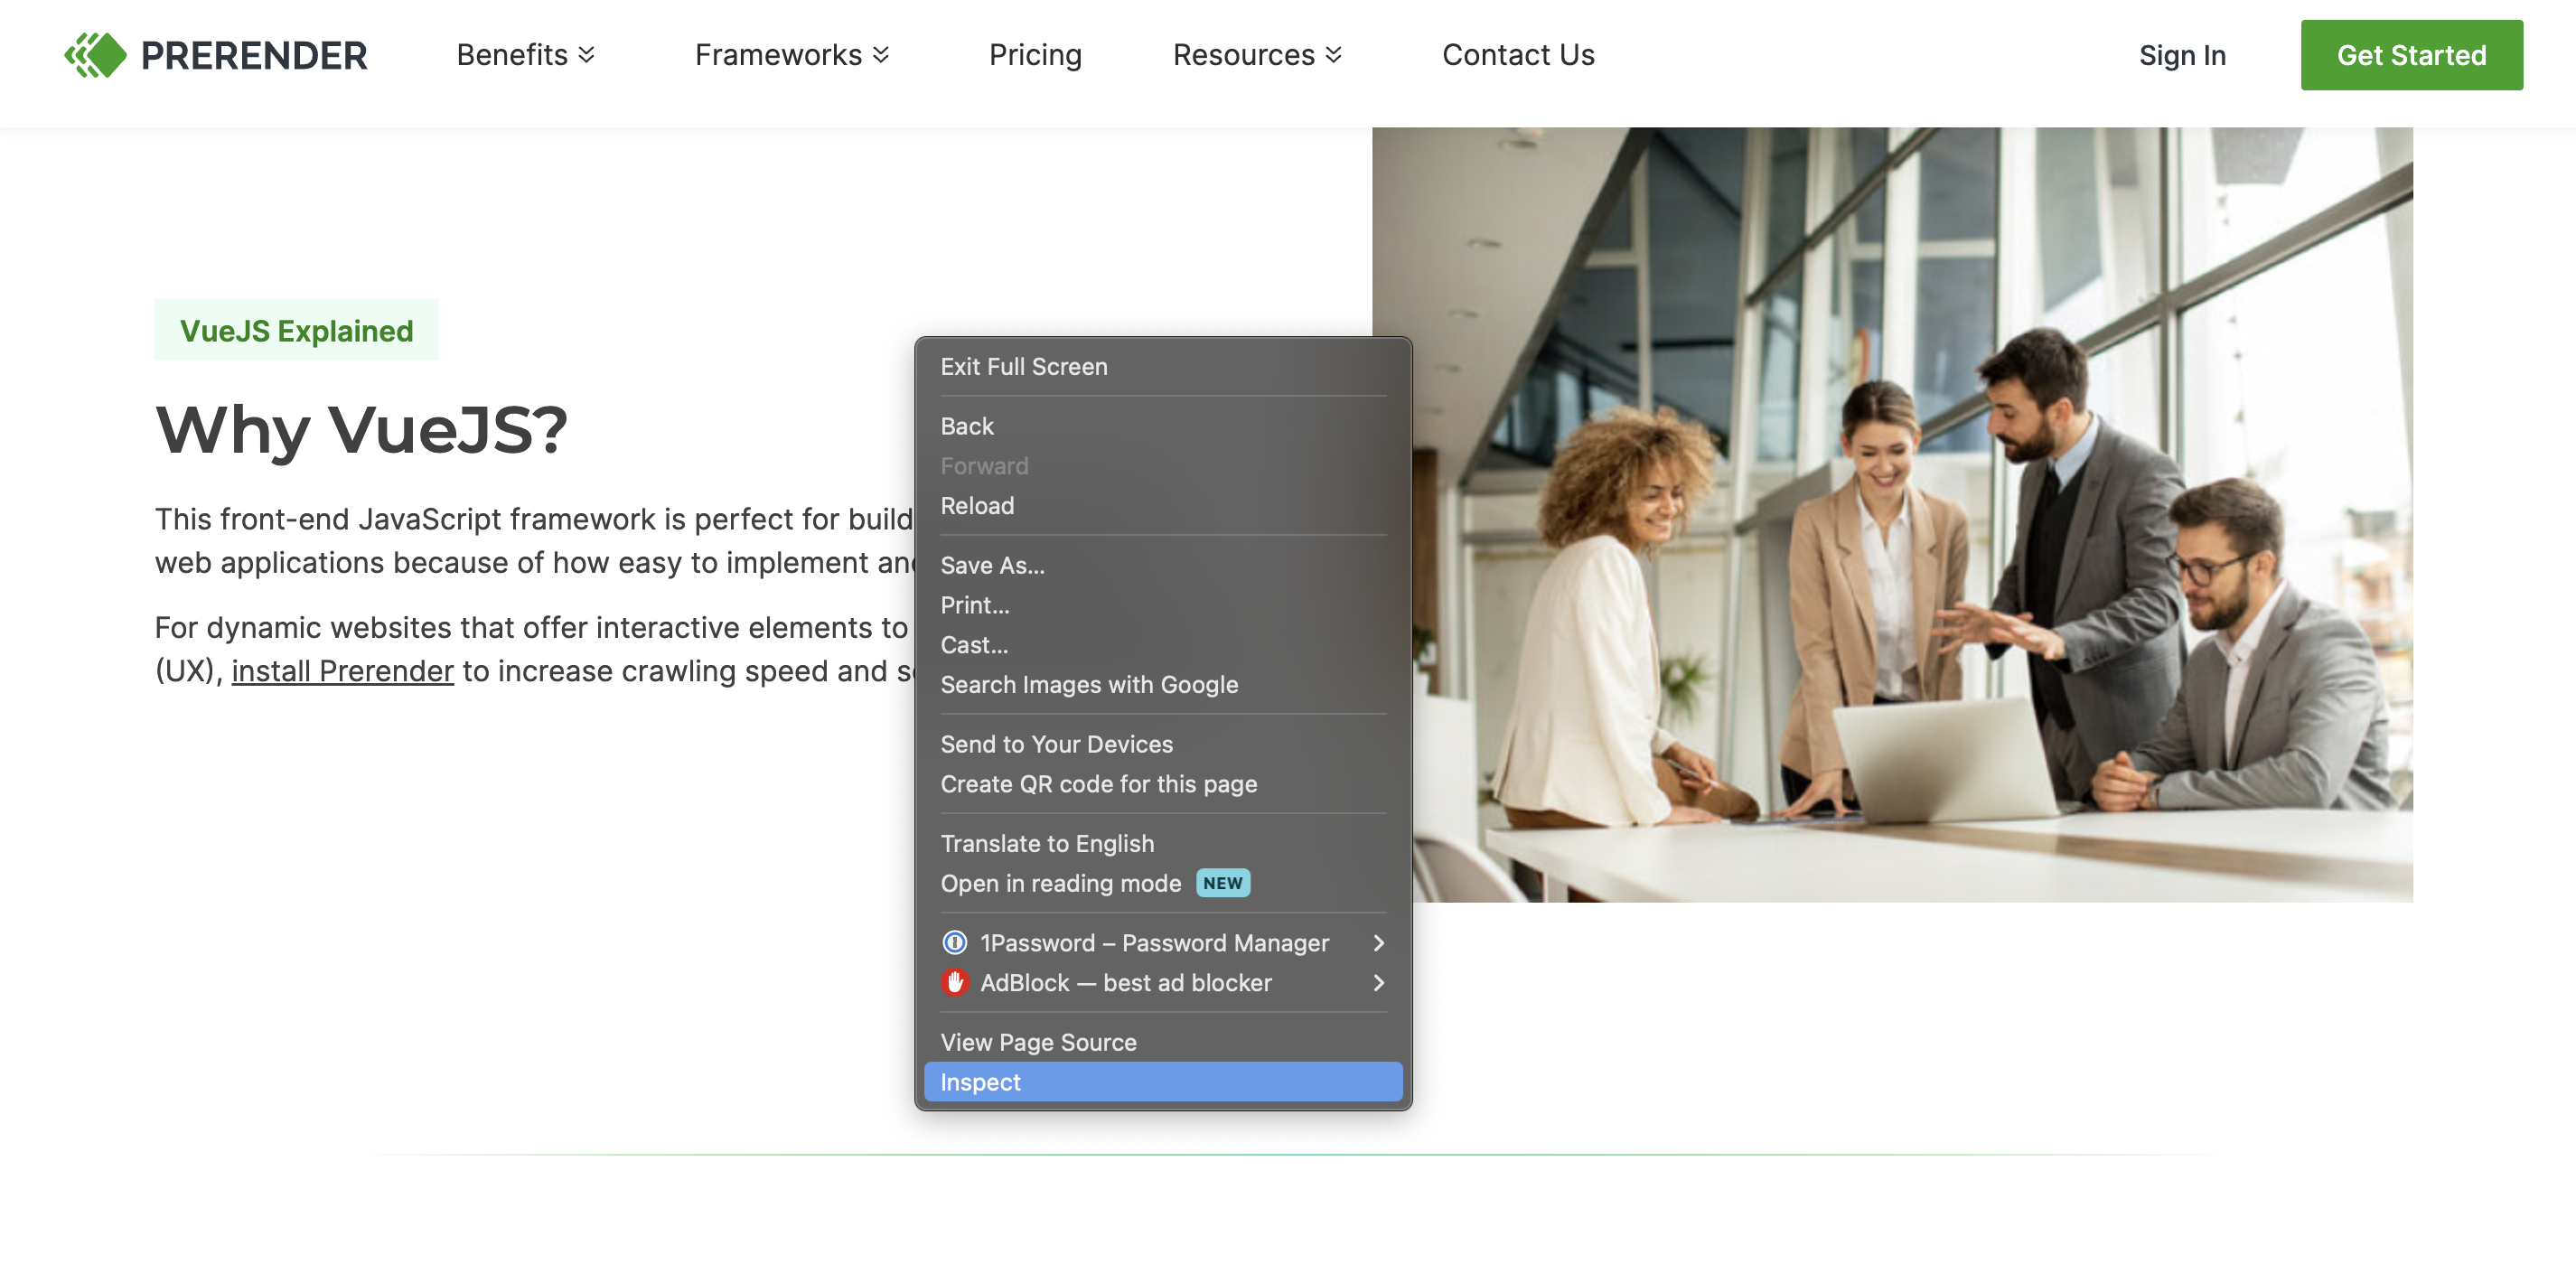
Head to the network tab and reload the page to see how your resources are loaded.
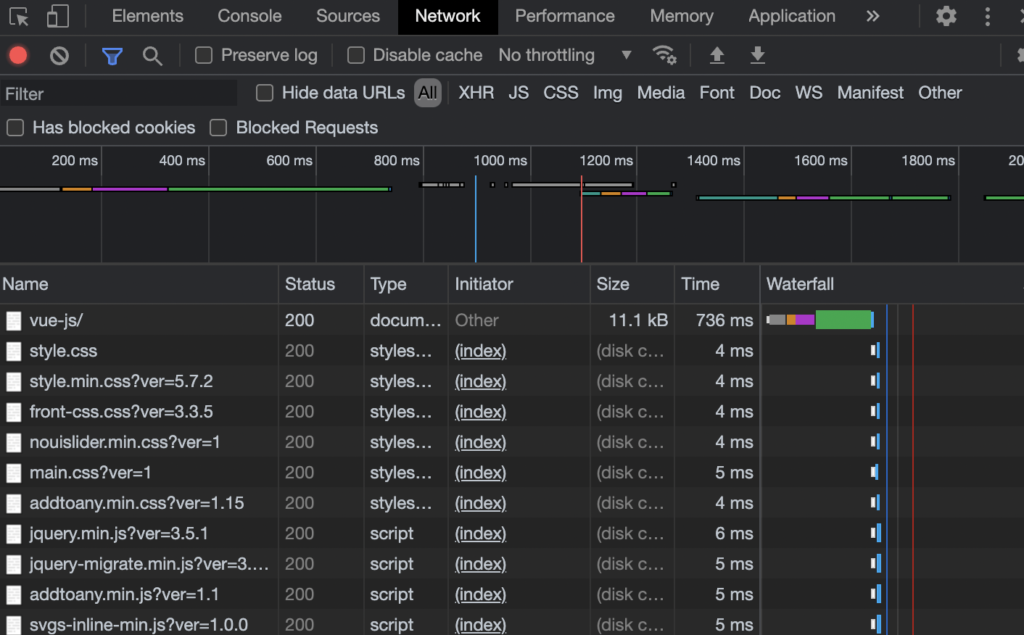
To test the importance of a resource, right-click on the resource you want to check and block it by hitting “Block request URL”.
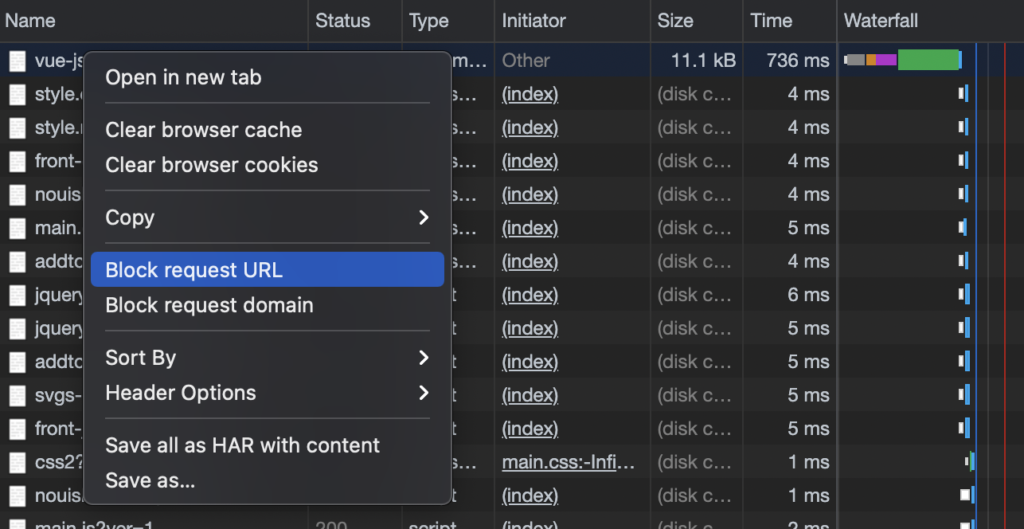
Reload the page. If any crucial piece of content disappears, you’ll need to change the robot.txt directive.
Use site: Searches as Supporting Evidence
You can also search for a URL and a distinctive phrase from the page:
site:example.com/products/running-shoes “breathable mesh upper”
This can provide a useful spot check, but a missing result is inconclusive. Google says site: results are not exhaustive and recommends URL Inspection for more reliable debugging.
For broader investigation, our guide to signs of JavaScript rendering problems connects rendering failures with the symptoms your team may already be tracking.
Make Crawler Access Part of Your Publishing Process
Making JavaScript SEO friendly requires a repeatable standard for what each page delivers.
We recommend agreeing on that standard with engineering: essential content is accessible, links expose usable destinations, metadata matches the URL, and updates reach the crawler-facing version within an acceptable timeframe.
Apply those checks to new templates and releases. That gives your team a way to prevent the same problems from returning.
If your application needs a practical way to deliver rendered content to crawlers, explore Prerender.io’s plans. We’ll help you evaluate the rendering and freshness requirements behind your search visibility goals.
See the results of when On, one of the world’s top running shoe companies, integrated with Prerender.io: indexing improved, traffic soared, and they saved millions of dollars per year. Read the full story.